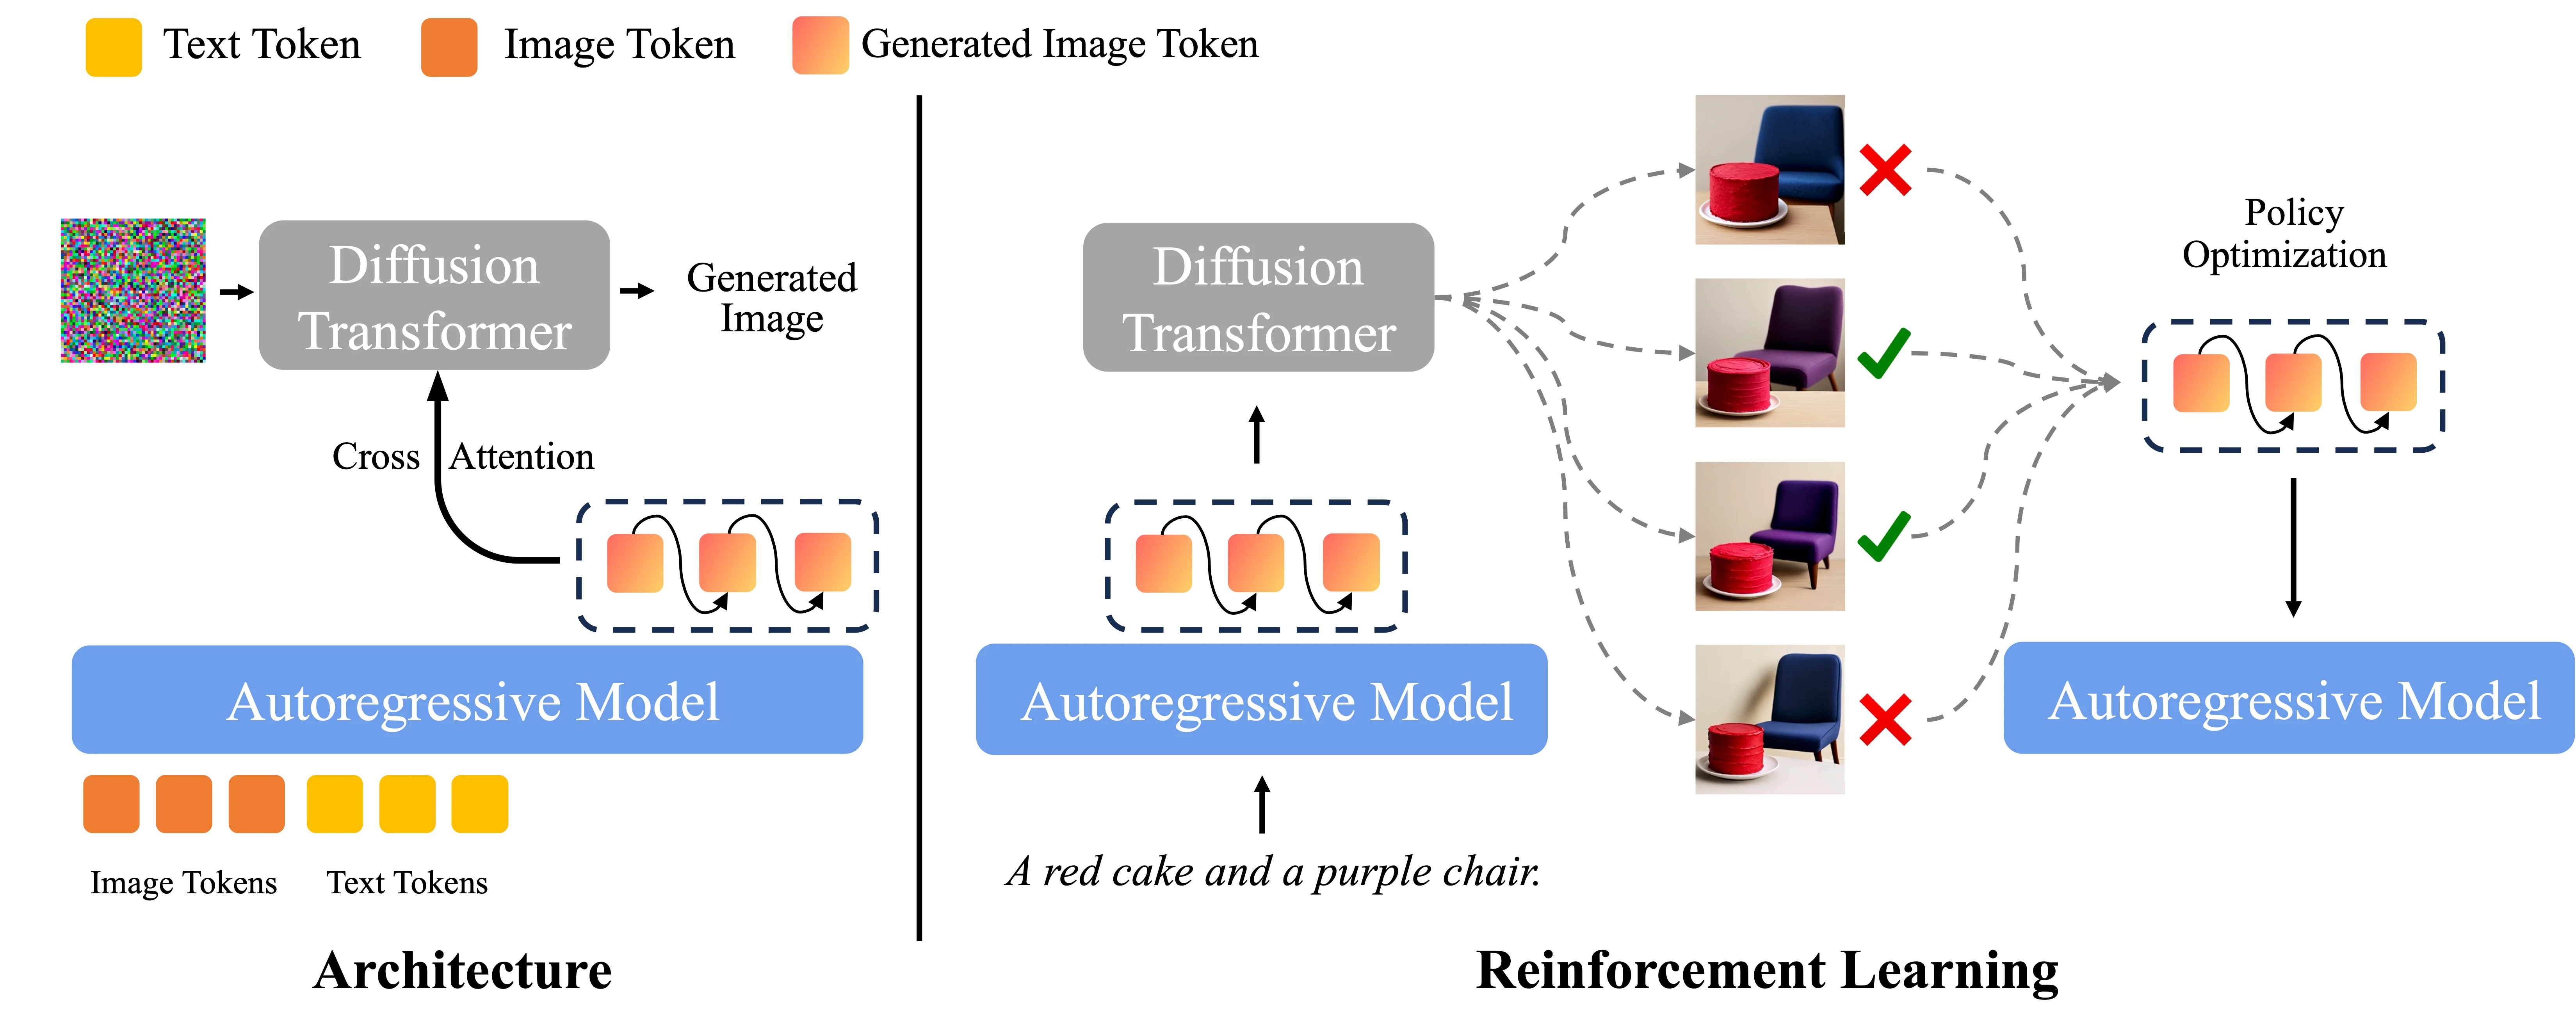
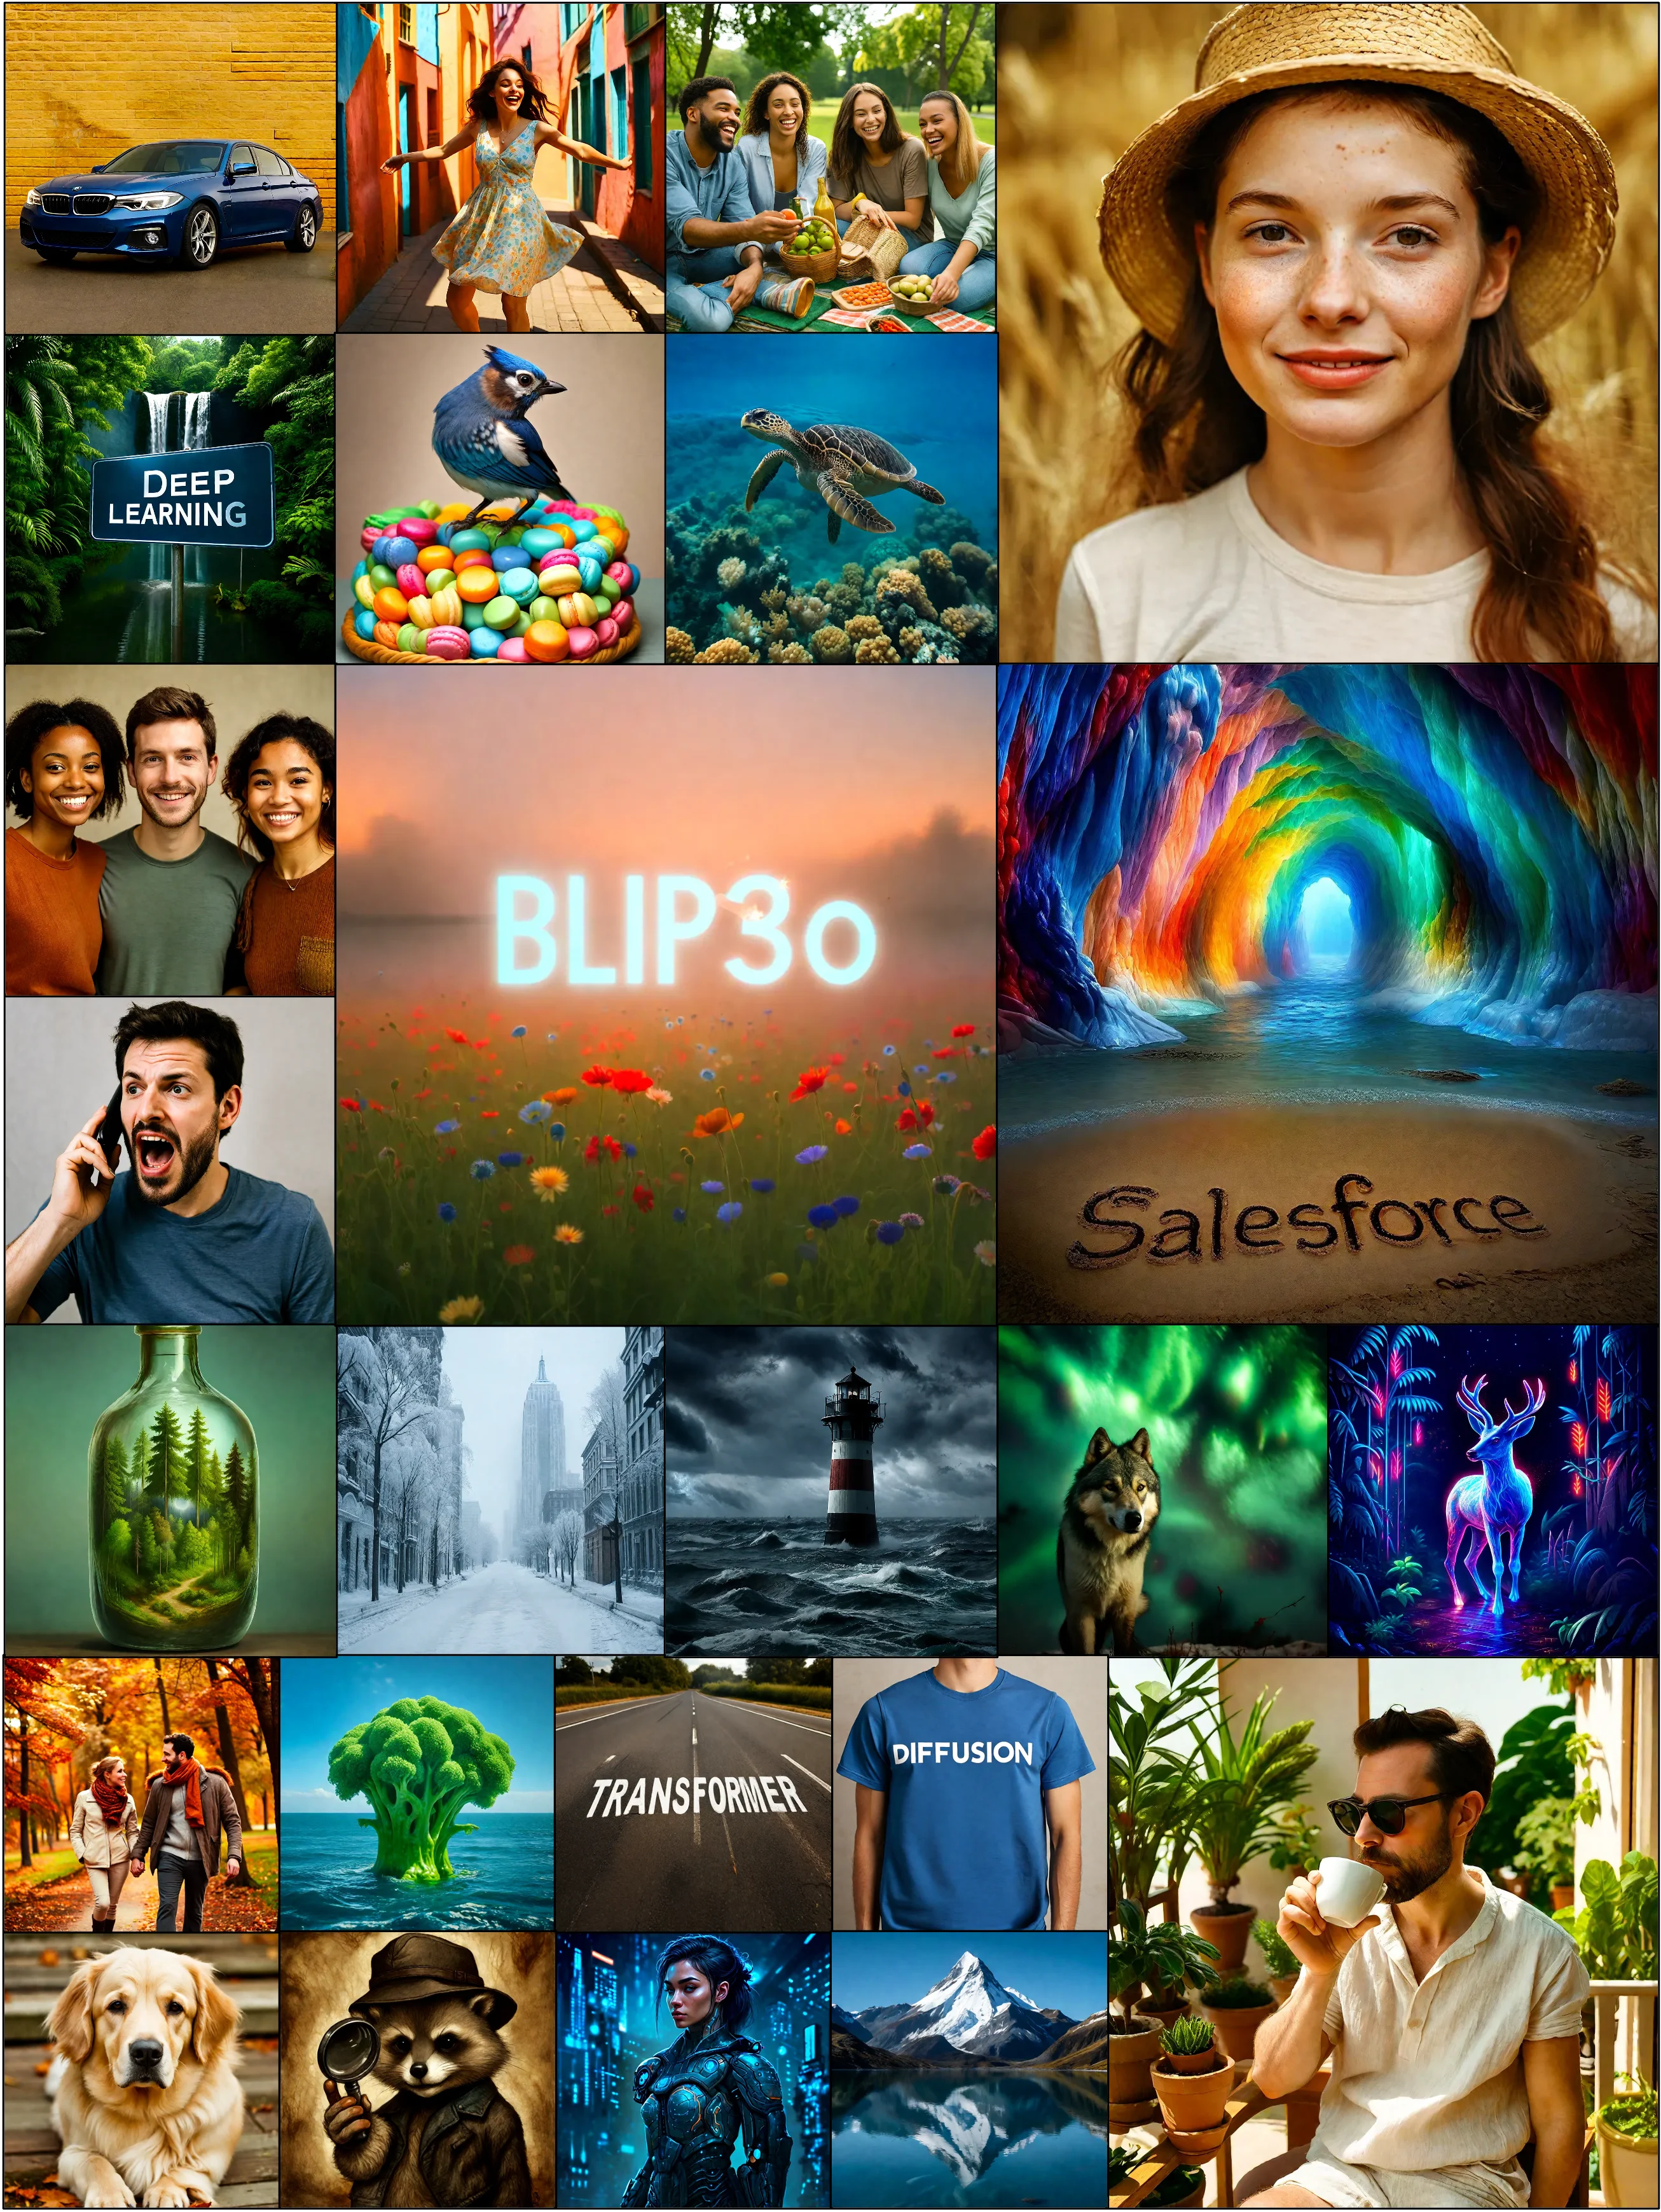
BLIP3o-NEXT: Next Frontier of Native Image Generation
* Equal contribution
An advance in native multimodal generation that improves visual fidelity, prompt alignment, and unified image understanding and creation.
I am a Senior Research Scientist at the MBZUAI Institute of Foundation Models (IFM) in Silicon Valley, working on video world model pretraining. I earned my Ph.D. from Virginia Tech, advised by Prof. Lifu Huang, with a dissertation titled Towards Unified and Generalizable Multimodal Foundation Models, after completing my B.S. at Rensselaer Polytechnic Institute. Previously, I interned at Meta GenAI and Apple AIML.
Selected research
Selected work in multimodal pretraining, understanding, and generation.
* Equal contribution
An advance in native multimodal generation that improves visual fidelity, prompt alignment, and unified image understanding and creation.
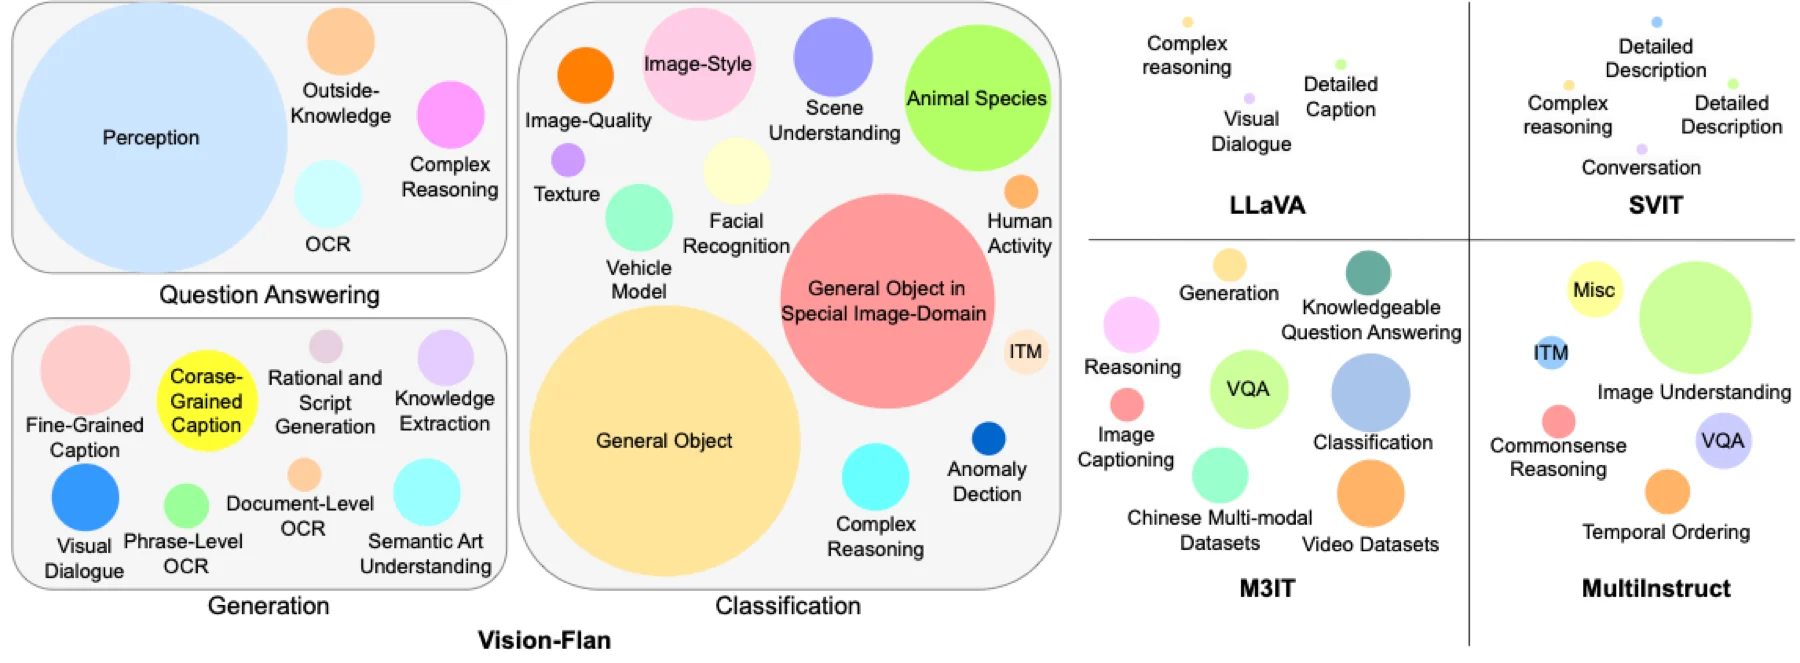
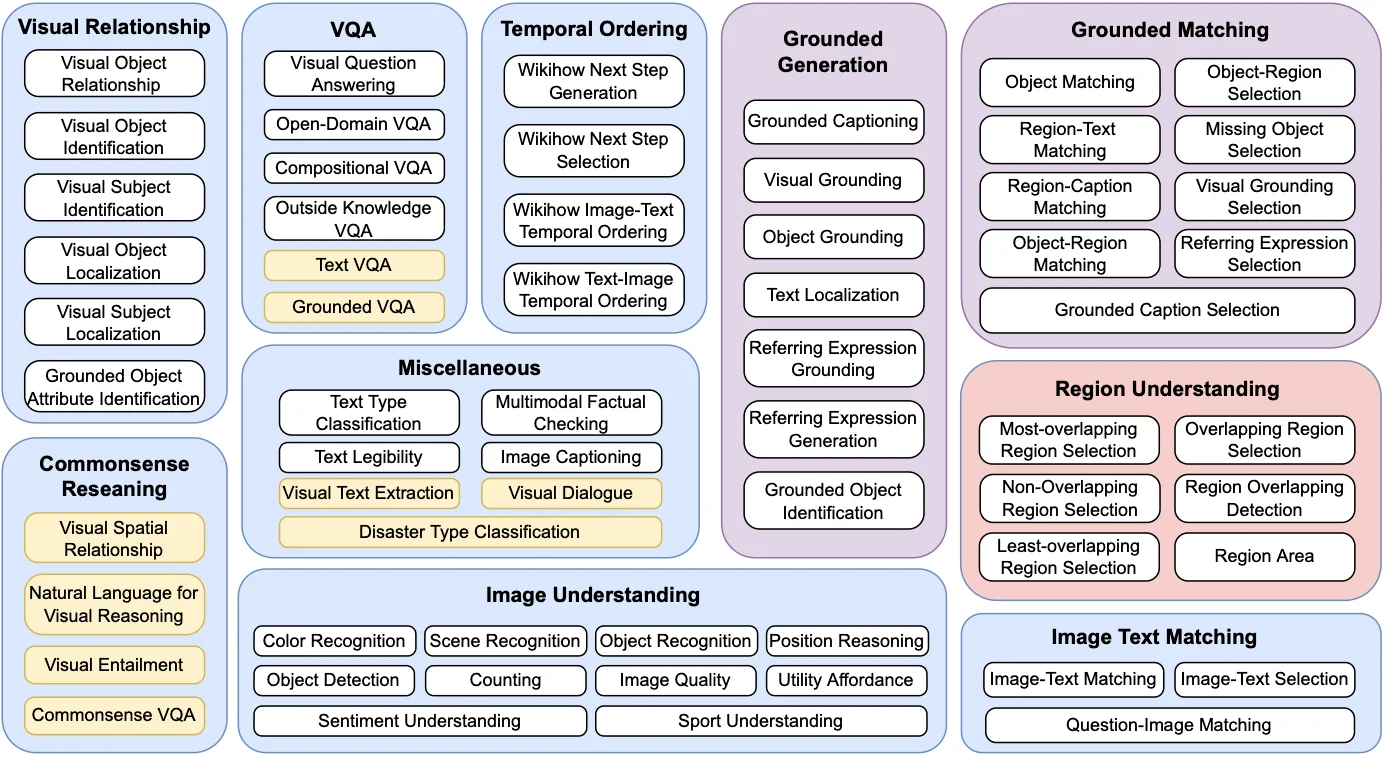
A large-scale visual instruction-tuning effort built from diverse human-labeled tasks to improve general multimodal instruction following.
* Equal contribution
Outstanding Paper Award
A multimodal instruction-tuning benchmark and training framework that improves zero-shot transfer across diverse vision-language tasks.